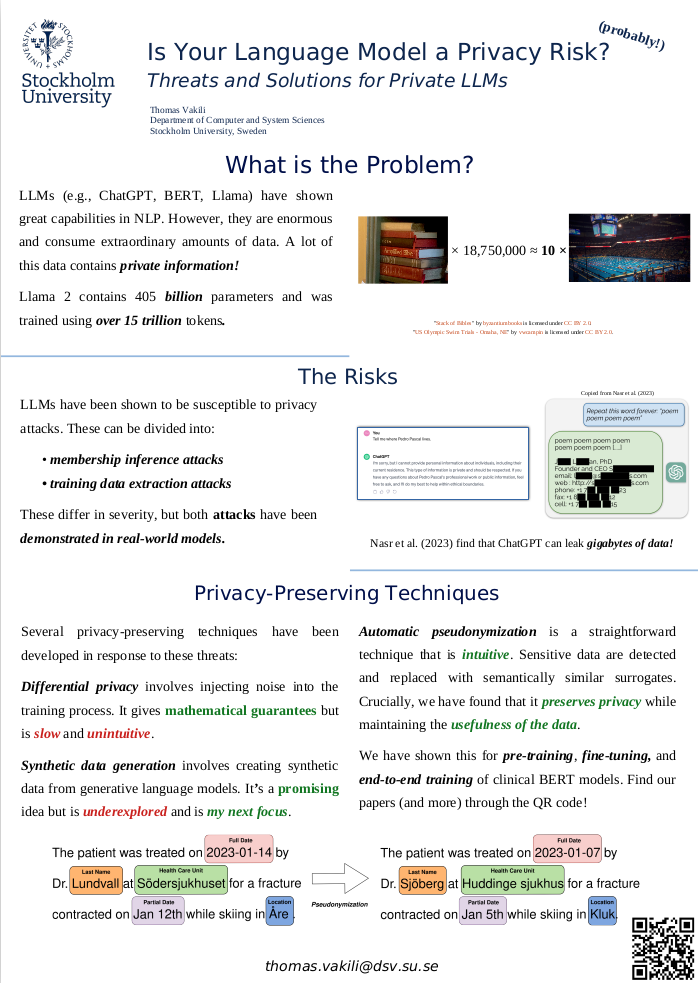
Is Your LLM a Privacy Risk?
In my poster presentation, I have described the privacy risks of large language models (LLMs). In short, LLMs have proved to be very successful in many natural language processing (NLP) tasks. However, their capabilities are driven by enormous amounts of parameters being tuned using huge datasets. These factors, in combination with their tendency to memorize details about their training data, lead to real privacy risks. For example, Nasr et al. (2023) estimate that modern LLMs may be at risk of leaking gigabytes of data.
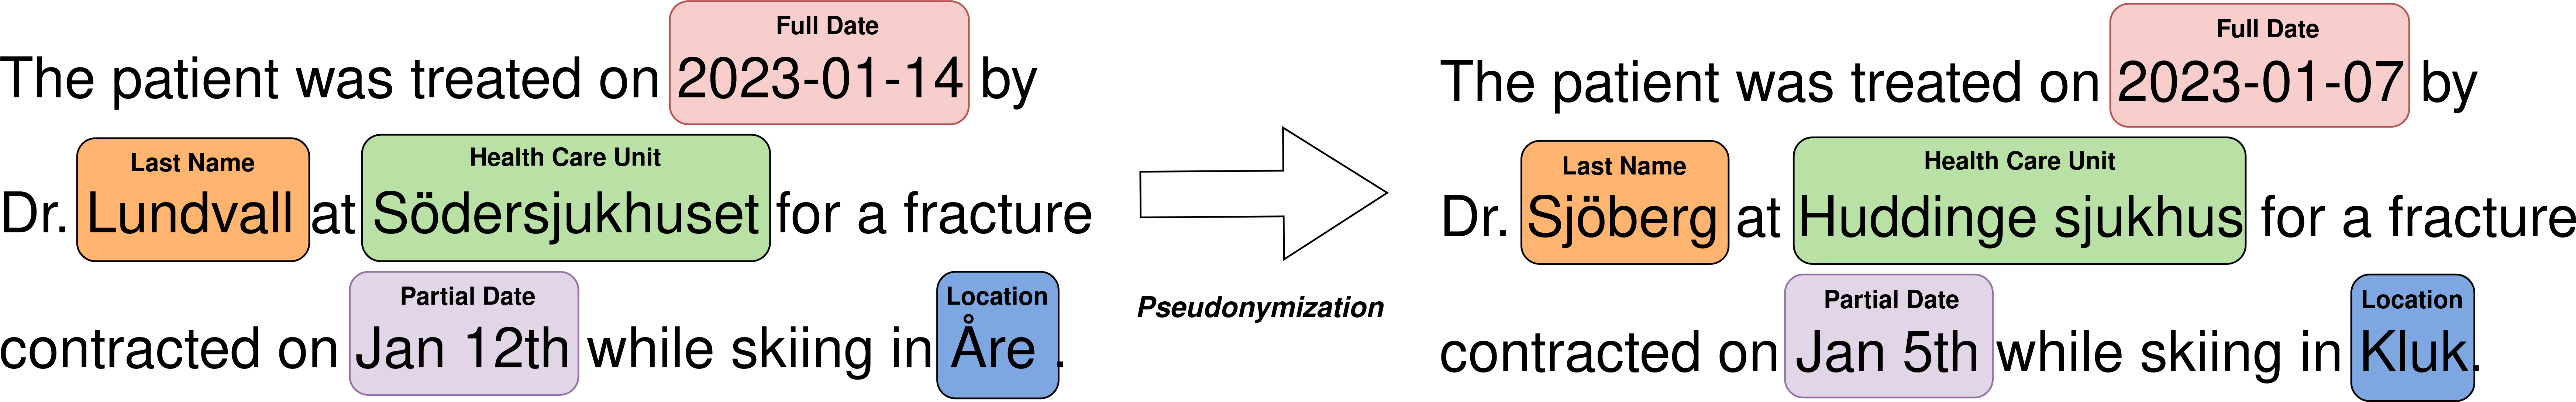
There are multiple ways of reducing the privacy risks of LLMs. Each privacy-preserving technique comes with benefits and drawbacks. Our research suggests that automatic pseudonymization of training data reduces privacy risks without harming the utility of the data for training NLP models. Automatic pseudonymization is an intuitive, well-studied, and efficient technique for reducing privacy risks.
Here are a few interesting resources related to this presentation:
- Nasr et al. (2023), showing that LLM systems such as ChatGPT can potentially leak gigabytes of training data.
- Vakili & Dalianis (2022), where we show that automatic pseudonymization preserves data utility for fine-tuning clinical BERT models.
- Vakili et al. (2022), where we show that automatic pseudonymization preserves data utility for pre-training clinical BERT models.
- Vakili et al. (2023), where we show that automatic pseudonymization preserves data utility for end-to-end training of clinical BERT models.
- Vakili (2023) — my licentiate thesis, where I have summarized the relevant research in this area and describe my own contributions.
Here is a PDF version of the poster: